Generative audio
SoloMuse
Listens to a backing track and generates a matching, steerable solo as real audio.
What it is
SoloMuse listens to a backing track and generates a solo that fits it, as actual audio. Unlike a black-box model, it plans the performance first (when to play, how dense, how tense, how loud), so the output can be steered.
How it works
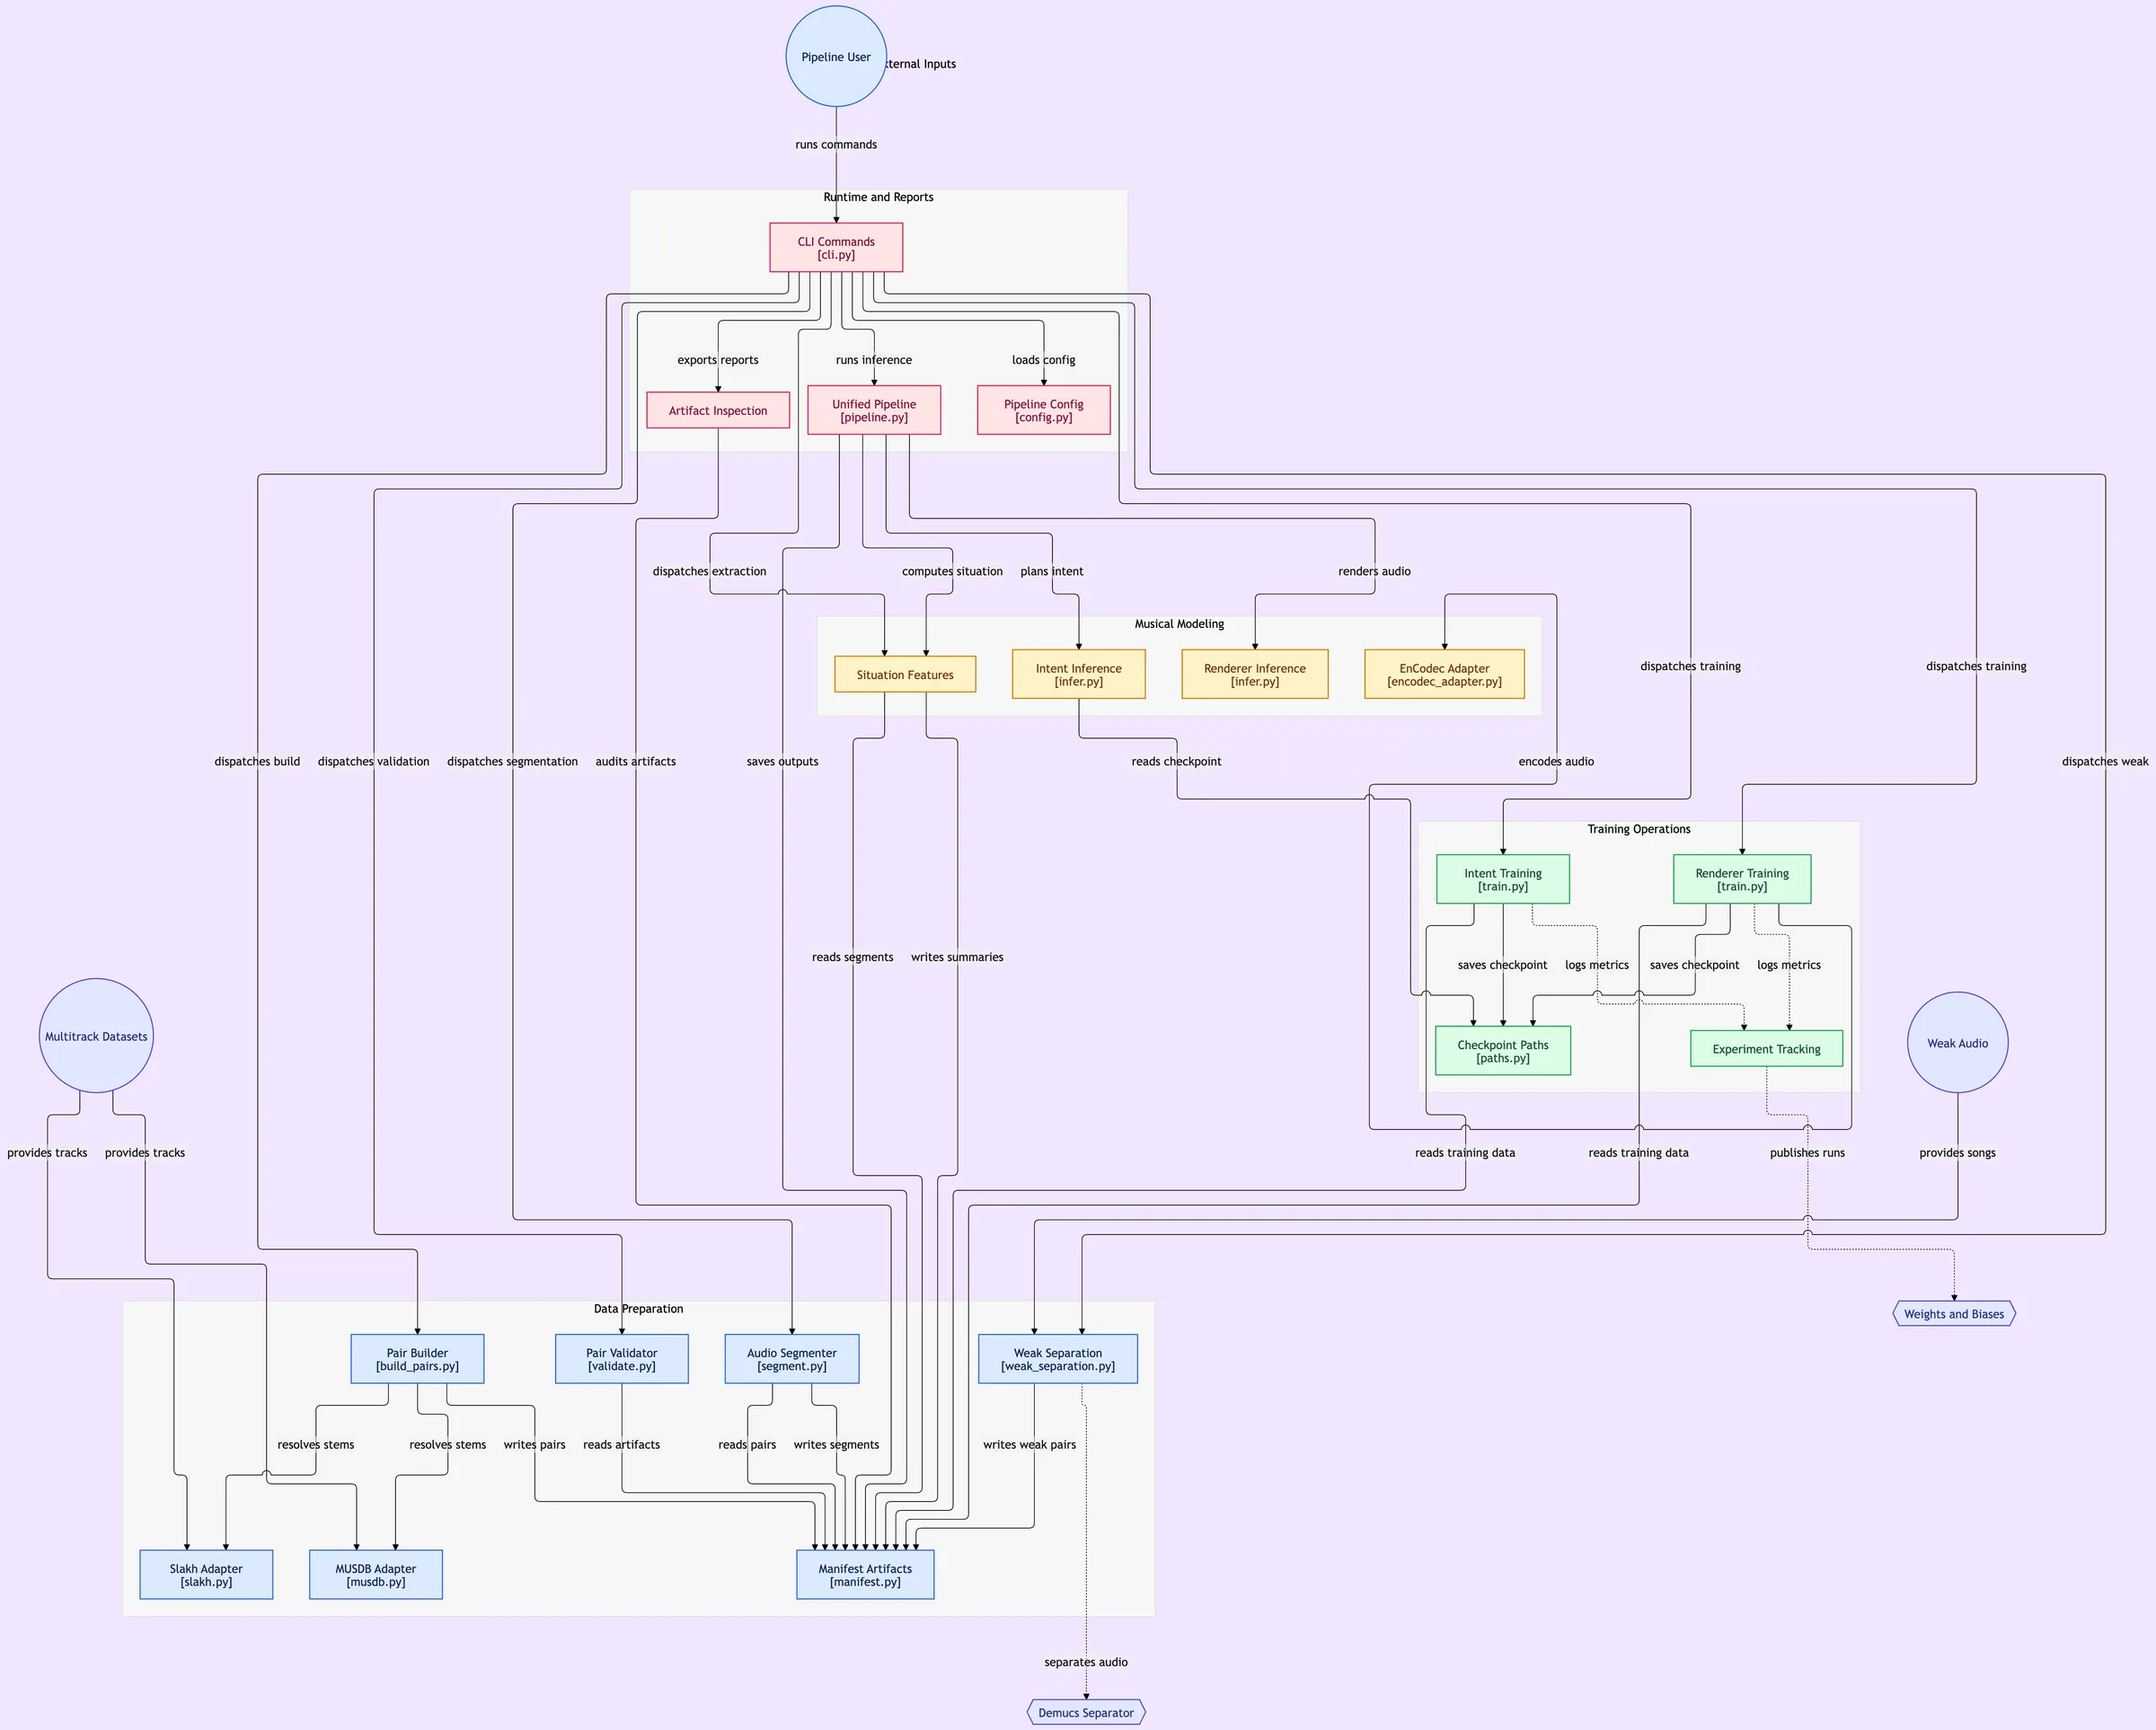
- Situation layer. Reads the backing track (tempo, loudness, harmony/chroma, spectral features) into a compact 32-number summary.
- Intent planner. A causal Transformer plans the musical intent 10 times per second: play or rest, note density, register, tension, dynamics, onsets and phrasing. You can override it, e.g. force more tension.
- Renderer. An autoregressive multi-codebook Transformer language model generates Meta EnCodec audio tokens (4 codebooks × 1,024 tokens at 75 Hz), which are decoded into a waveform.
Data pipeline
- Slakh2100 and MUSDB18 multitrack datasets, plus optional raw songs split into stems with Demucs.
- Stem pairing, EBU R128 loudness normalization (−18 LUFS), peak limiting and mix-consistency checks.
- 6-second windows, and track-grouped train/val/test splits (MD5 hashing) so no song leaks across splits.
Engineering highlights
127automated tests
3model layers
A100cloud GPUs on RunPod
250 msstreaming chunks
- Numerical stability guards for FP16 / Apple Silicon (activation clamping, skipping steps on huge gradients, crash dumps).
- A one-click RunPod script that downloads data, builds everything, trains both models and verifies the result, and resumes if interrupted.
- Docker support and a live streaming mode with overlap-add.